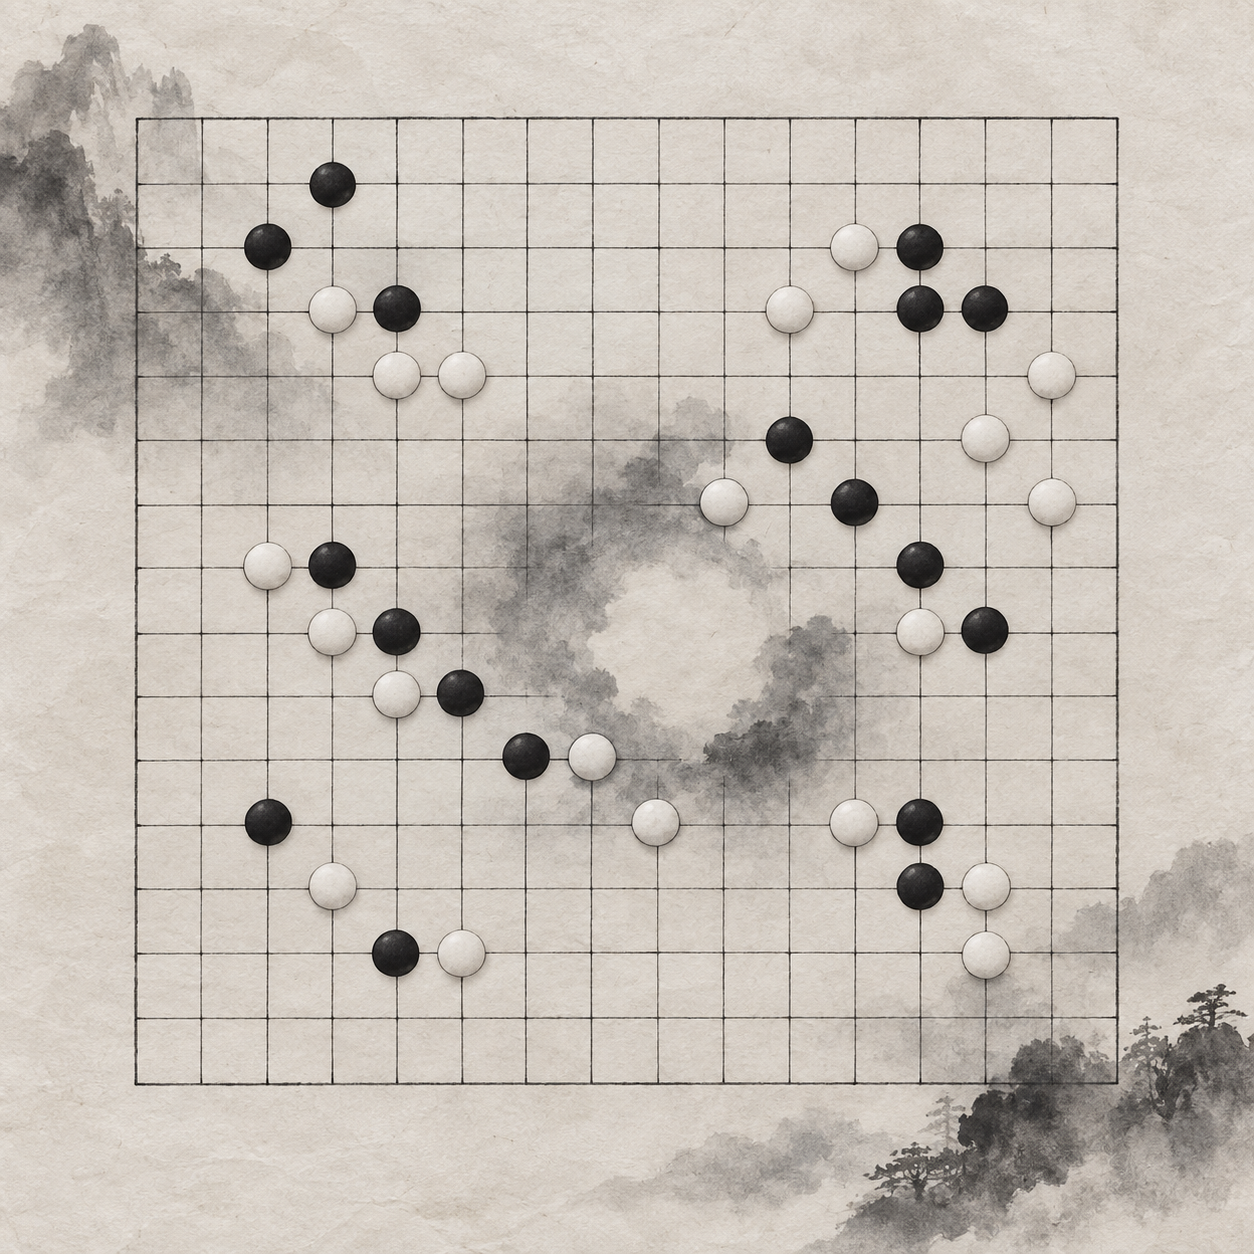
Black places a stone near the middle of the board. White faces no four-in-a-row that demands an immediate block, but two diagonals are beginning to converge. The engine favors a defensive move away from their intersection. If you count only the patterns already on the board, you may wonder what it sees.
When search stops, evaluation takes over
An engine searches ahead through candidate moves and possible replies. In alpha-beta search, for example, it prunes branches that no longer need checking. It still cannot follow every branch to the end of the game.
When search stops at a position, an evaluation function scores that leaf node so the engine can compare moves higher up the tree. Black’s diagonal may pose no immediate threat, yet the score might suggest that White will struggle to cover both sides later. Search uses that estimate to decide whether the line is worth pursuing.
The score estimates the current position; the moves to come will decide the game. The earlier a search stops, the more its evaluation must recognize connections that have not yet become threats but will shape later choices.
What a hand-written pattern table sees
A traditional evaluation recognizes shapes such as an open three or a four-in-a-row, then adds up preset weights. The logic is legible: a four-in-a-row usually demands attention before a shape that needs another preparatory move. An engine can use that distinction to check defensive moves first.
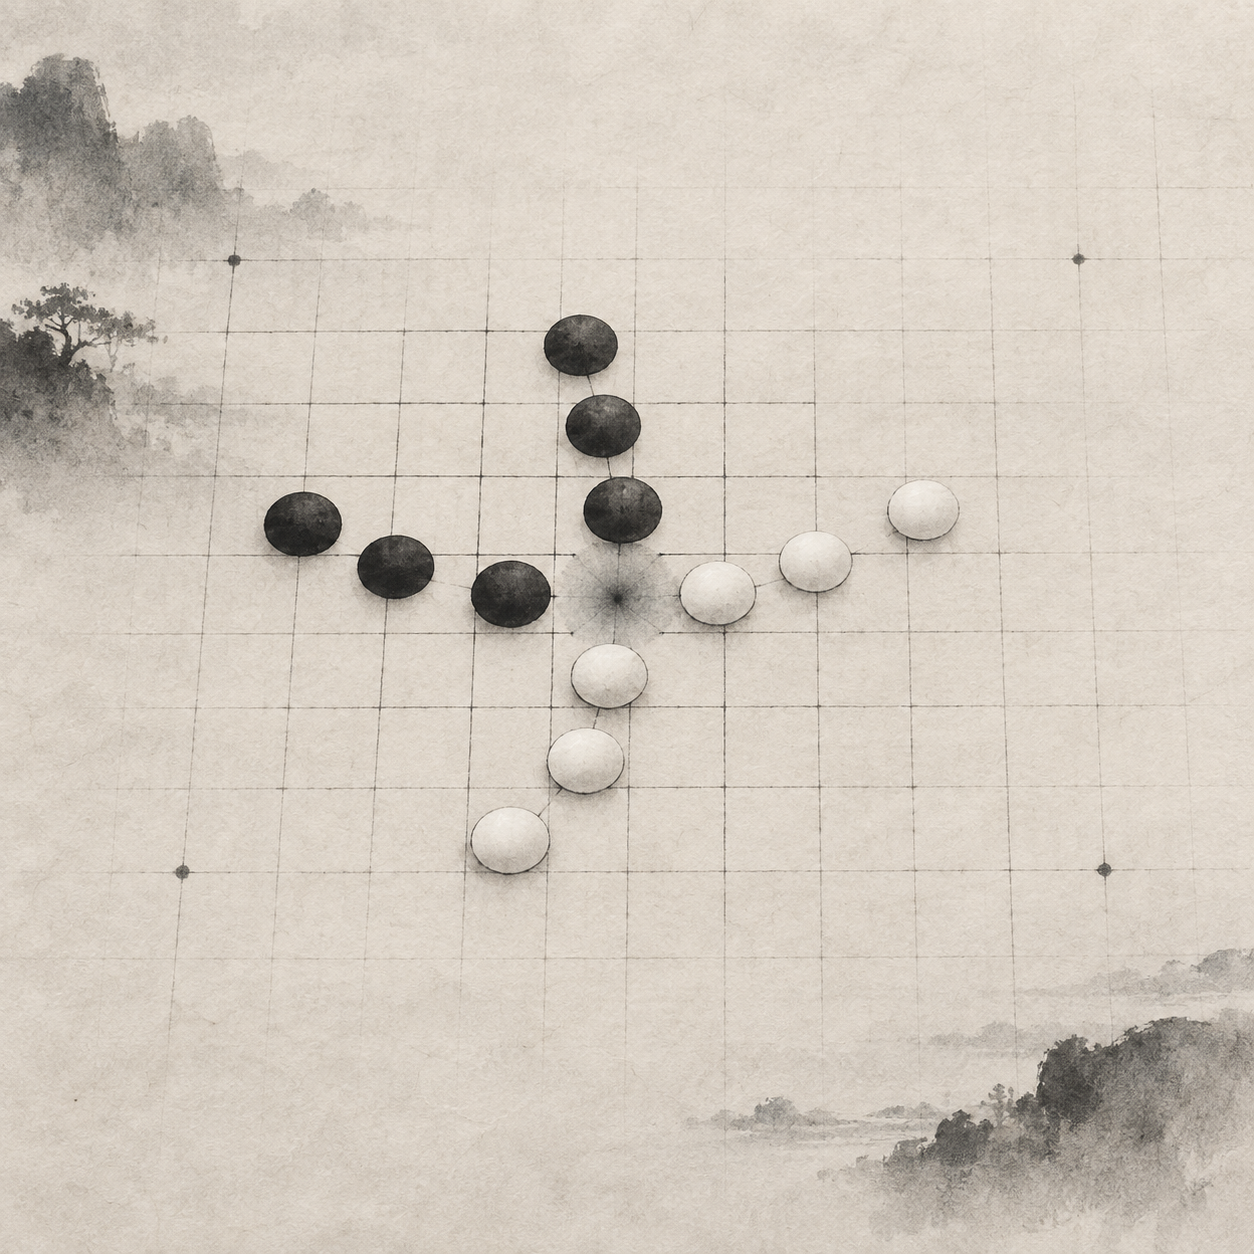
Consider a 15×15 freestyle position with White to move. Black has a diagonal shape in the upper left and a horizontal one on the right, both extending toward the empty tengen. A White stone on tengen answers both. If a hand-written table scores the shapes separately and assumes each requires its own defense, it counts the defensive cost twice and overvalues Black’s position. Such a table is also limited to shapes its author anticipated. Search can catch some omissions, but only after expanding the relevant branches. If an early evaluation pushes a crucial move aside, the engine may never spend enough time on that line.
From written rules to trained judgment
NNUE stands for “efficiently updatable neural network.” According to public accounts of NNUE’s origins in the shogi engine YaneuraOu, Yu Nasu invented it in 2018 and first used it in YaneuraOu. Its name also echoes the pronunciation of the nue, a creature of Japanese legend. NNUE lets an engine update a trained evaluation relatively quickly after each move—a useful property when search must score positions again and again.
Chess offers a useful comparison. According to public engine records for Stockfish NNUE, by August 2020 it searched at roughly half its former speed yet played at least 80 Elo stronger than it had with traditional evaluation. It was then adopted by the official engine. A better judgment at the leaves can sometimes outweigh a slower search.
Evaluation can change; search still has to test the line
A learned judgment still needs testing
A trained evaluation can learn how patterns work together across many positions. It remains an estimate. If White has a four-in-a-row that demands a reply, Black’s apparent positional advantage may vanish quickly. The engine still has to search through that forcing sequence.
Search methods divide the work differently. PVS fully searches its preferred move first, then tests other moves with a narrow window, searching again when necessary. Monte Carlo tree search devotes more simulations to promising branches. For sequences of continuing threats such as VCT, some engines use proof-number search to check whether a forced attacking line exists.
A move can enter the shortlist on the strength of its evaluation, then fall away when search finds a concrete reply. When an engine changes its mind, look first for the move that changed the threats. Comparing the two scores alone tells you less.
Different combinations at Gomocup 2026
The engine updates on the official Gomocup 2026 results page describe several combinations. Figrid pairs alpha-beta search with NNUE evaluation and uses a threat cache and continuation history to order moves. Chloris trained its own NNUE on about three million Standard-15 positions; alongside search, it has checks for forcing moves and a layer for urgent defense.
The same official Gomocup 2026 page notes that TKGomoku retains a hand-written pattern evaluation while also using a lightweight NNUE, a policy file and an opening book. DDQK-Conquer uses an NNUE-like algorithm. Starpoint pairs Monte Carlo tree search with transformer evaluation and uses proof-number search internally for VCT. Trained judgment appears in several architectures, but not in the same role.
Nor can the results be credited to any one kind of evaluation. According to the official Gomocup 2026 results page, RAPFI retained its 20×20 freestyle title in 2026 and won both 15×15 freestyle and blitz. New entrant KATAGOMO finished second in both freestyle divisions, trailing by just 9 Elo in 15×15. Evaluation, search and time management all shape how an engine plays.
Reading a surprising recommendation
An engine may rank a quiet move ahead of one that immediately forms a three because the quiet move also restricts two future lines. A hand-written pattern table may see no high-scoring shape when the stone lands. A trained evaluation may give more weight to the relationship between the shapes. Whether that judgment holds up depends on the replies search finds.
Read a score in context. The rules, search depth, time available and evaluation method all affect it. Another engine may give the same position a different number and a different move order. Look at how both sides play after the recommendation, then ask whether the score gap holds.
Bring the score back to the board
When reviewing a game, find the threats that demand an answer before studying the more distant connections. If a move creates no immediate four-in-a-row but leaves the opponent able to defend only one side on the next turn, note when that constraint first arose.
Evaluation changes how an engine selects and judges positions. Search remains responsible for testing the moves that follow. Keep those jobs separate, and an unfamiliar recommendation invites two sharper questions: What does it value, and how far has it checked?
Check the forcing moves before you trust the score